Programmatic SEO Architecture: Enterprise Database Search Scale
Fast Track Summary
- Architect Scalable Data Schemas: Shift from static page creation to structured database engines, transforming intent datasets into distinct, programmatic landing pages.
- Protect Crawl Budget & Indexation: Implement strict canonical hierarchies, dynamic XML sitemaps, and strategic internal linking to prevent index bloat and duplicate content penalties.
- Optimize for Answer Engines (AEO): Structure database outputs with structured schema markup, enabling AI crawlers like ChatGPT, Perplexity, and Google AI Overviews to parse and cite your pages.
Most mid-market growth teams burn hundreds of thousands of dollars manually producing static landing pages. They build fifty location pages or twenty product-comparison layouts, run out of content resources, and plateau.
Meanwhile, enterprise platforms quietly capture millions of high-intent organic visitors by turning structural data into dynamic web pages.
Programmatic SEO architecture is not about spinning low-quality, AI-generated text over a surface-level template. It is an enterprise-grade engineering discipline that pairs structured database design with search engine crawl optimization.
When executed correctly, a programmatic SEO architecture builds thousands of uniquely valuable, search-engine-optimized pages that capture long-tail search intent at scale.
What Is Programmatic SEO Architecture and How Does It Scale?
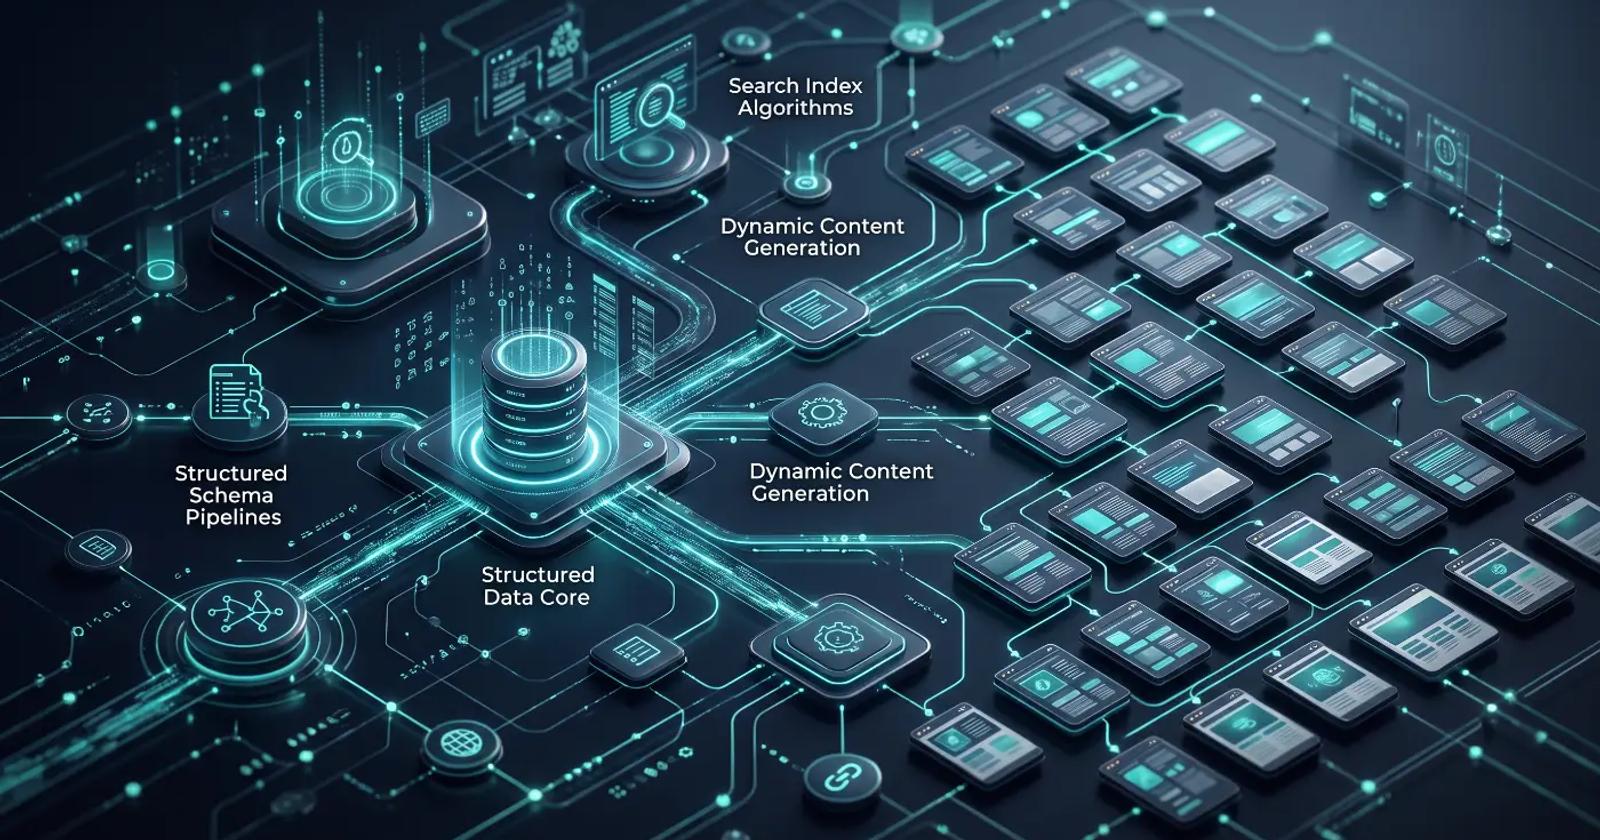
Programmatic SEO architecture is an enterprise engineering framework that uses structured databases, automated page templates, and dynamic site mapping to automatically generate hundreds or thousands of unique, search-optimized web pages. By mapping transactional intent data to programmatically rendered frontend pages, companies can systematically capture vast clusters of long-tail search queries without incurring manual content creation overhead or triggering duplicate content penalties.
The programmatic architecture operates as an interconnected, three-stage processing pipeline that continuously converts system data into organic search visibility:
- The Intent Database: Raw entity records, localized variables, and transactional attributes are unified into a normalized data store.
- Dynamic Templates: Frontend page layouts ingest these underlying datasets, applying conditional rendering logic, dynamic content variations, and structured JSON-LD schemas.
- The Algorithmic Crawl Engine: Server-side rendering pipelines output these pages alongside dynamic XML sitemaps and automated internal linking networks, delivering fully realized, unique long-tail landing pages directly to search engine crawlers.
Decoupling Content Generation from Human Hours
Standard content strategies rely on human writers building pages one by one. This manual bottleneck limits market coverage and balloons customer acquisition costs.
Programmatic systems decouple page creation from human labor hours. You build the underlying data model, code the rendering template, and let your database populate your site's physical page structure.
A mid-market home services rollup, for example, cannot realistically write 2,500 unique pages by hand for every service-city combination it serves.
By building a structured database of localized pricing ranges, regional compliance requirements, local climate considerations, and service parameters, a single developer can programmatically deploy thousands of distinct landing pages.
This model relies heavily on high-performance search engine optimization systems engineered to support heavy dynamic indexing.
Long-Tail Intent Dynamics at Enterprise Scale
Search queries follow a power-law distribution that separates high-level broad searches from nuanced, highly targeted commercial actions across two primary tiers:
- Head Keywords: High-volume search terms like "CRM Software" represent top-of-funnel broad intent. These terms feature immense search competition, astronomical customer acquisition costs, and relatively low conversion rates due to mixed user intent.
- Long-Tail Keywords: Highly specific phrases like "HIPAA Compliant CRM for Medical Recruiting Agencies in Texas" capture explicit transactional intent. While individual search volume per phrase is lower, long-tail terms carry minimal competition and produce significantly higher conversion rates because the offer perfectly matches the searcher's parameters.
Long-tail searchers exhibit explicit, commercial intent. They know their exact problem, their localized constraints, and their budget requirements.
Programmatic architecture allows enterprise brands to intercept these high-converting queries by building programmatic page targets for every permutation of an intent cluster.
Database Entities vs. Static Blog Articles
Traditional content marketing relies on unstructured blog articles that treat topics as isolated silos. Programmatic SEO treats content as structured, relational entities within a relational or document database.
Every record in your database represents a discrete entity with specific, queryable attributes:
- Location Entities: City, state, zip code, regional regulations, local climate data, nearest branch, local average project costs.
- Comparison Entities: Competitor name, core feature gaps, pricing tier differences, target audience size, user rating distributions.
- Market Sector Entities: Industry verticals, compliance standards, core integrations, pre-built workflow templates.
When your site renders, your dynamic templates fetch these specific database variables and inject them into structured, semantic HTML layouts.
This database-driven approach requires a seamless integration between back-end data pipelines and modern custom website design frameworks capable of server-side rendering at speed.
Modern Answer Engine Optimization (AEO) Integrations
Search engines have evolved from keyword matching systems to generative answer engines. Platforms like Google AI Overviews, Perplexity, ChatGPT, and Gemini rely on clear entity relationships to extract data for AI summary blocks.
Programmatic pages engineered with structured JSON-LD data schemas act as ideal data feeds for LLM crawlers.
When your programmatic template dynamically outputs structured Product, Service, LocalBusiness, or FAQPage schema markup alongside clean tabular content, answer engines can index your core data values directly.
This ensures your enterprise brand earns top-of-page citations in generative answers alongside standard SERP positions.
How to Build a Enterprise-Grade Programmatic SEO System
To construct a programmatic SEO system, engineering teams must execute five steps: structure a normalized entity dataset, design variable-driven page templates with conditional display logic, deploy server-side rendering (SSR) for crawl speed, implement canonical and internal linking rules to protect crawl budget, and publish dynamic XML sitemap trees for fast indexation.
Engineering teams can safely build and scale an enterprise programmatic deployment by executing a sequential five-stage development roadmap:
- Structure Entity Datasets: Audit internal databases, normalize data fields across all entity records, compile localized variables, and scrub incomplete entries to prevent thin content generation.
- Design Conditional Templates: Build semantic HTML page layouts using variable string tags, conditional component rendering, array-driven content variations, and dynamic call-to-action routing.
- Deploy Server-Side Rendering (SSR): Implement Server-Side Rendering (SSR), Static Site Generation (SSG), or Incremental Static Regeneration (ISR) to deliver raw HTML directly to search bots on initial request.
- Enforce Internal Linking & Canonicals: Establish clear parent-child directory hierarchies, implement self-referential canonical tags, deploy horizontal peer-to-peer linking modules, and apply automated
noindexrules to thin parameter pages. - Deploy Dynamic XML Sitemap Trees: Segment generated URLs into structured sitemap index files capped at 50,000 URLs per sub-sitemap to streamline crawl budget allocation and indexation speed.
1. Data Normalization and Structuring Entity Datasets
The foundation of any programmatic engine is clean, structured data. If your underlying database contains missing fields, inconsistent naming conventions, or duplicate records, your programmatic pages will feel low-quality, incomplete, or repetitive.
Start by auditing your internal data assets or sourcing reliable external data feeds. Normalize every attribute across your database to ensure consistency across all entries:
- Primary Key: A unique identifier for every database entry (e.g.,
loc_austin_tx_042). - Core Variables: Essential string variables required on every page (e.g.,
City_Name,State_Abbreviation,Average_Cost). - Secondary Dataset Arrays: Nested datasets used for tables, lists, or conditional blocks (e.g.,
Local_Regulations_List,Top_3_Industry_Integrations). - Calculated Metrics: Dynamic values generated via formulas (e.g., calculating local cost estimates based on regional inflation modifiers).
A multi-thousand dollar mistake engineering teams routinely make is launching programmatic pages with incomplete datasets.
If a database record is missing 40% of its variables, the rendered page outputs empty space or broken layouts, signaling low content quality to search crawlers.
Every record must pass a data-completeness validation check before its corresponding URL is compiled into your public site build.
2. Variable-Driven Templates with Conditional Logic
A programmatic template is an HTML layout wired with dynamic placeholder tags and conditional execution rules.
To prevent pages from triggering duplicate content flags, your templates must adapt dynamically based on the underlying dataset for each record.
Do not rely solely on simple string replacement (e.g., swapping out city names inside identical prose). Implement deep conditional logic within your templating engine:
- Conditional Section Rendering: Render specific sub-sections only when unique data conditions are met (e.g.,
IF local_permit_required == TRUE, render_permit_section()). - Variable Text Variations: Construct array-based phrase variations that dynamically alter sentence structure based on data attributes, maintaining high content variance across programmatic URLs.
- Dynamic Media Assets: Programmatically pull context-specific images, interactive visual charts, or localized map embeds based on entity parameters, avoiding static placeholder images across generated pages.
- Custom Call-to-Action (CTA) Routing: Dynamically point lead forms to specific sales teams or specialized onboarding flows based on industry, geographic territory, or account tier.
For B2B brands using programmatic landing pages to drive customer pipelines, pairing dynamic content variations with tailored B2B lead generation systems maximizes conversion efficiency across diverse intent clusters.
3. Server-Side Rendering (SSR) vs. Client-Side JavaScript
One of the most dangerous technical risks in programmatic SEO is relying on client-side rendering (CSR) frameworks.
When single-page application (SPA) frameworks render content entirely via client-side JavaScript, search engine crawlers often fetch an empty HTML shell.
While Google claims to render JavaScript, crawl budget constraints often lead to delayed indexing or skipped page evaluations on massive SPA deployments.
- Client-Side Rendering (CSR) Risks: A search crawler requests a page, receives an empty HTML shell, and must execute heavy client-side JavaScript bundles to view the content. This frequently leads to execution timeouts, delayed indexation, or complete page omission during crawl passes.
- Server-Side Rendering (SSR) Benefits: A search crawler requests a page and immediately receives a fully pre-rendered, semantic HTML document from the edge server. Content is indexed instantly on the initial pass, eliminating rendering latency and conserving domain crawl budget.
Enterprise programmatic deployments require Server-Side Rendering (SSR) or Static Site Generation (SSG).
- Static Site Generation (SSG): Pre-compiles HTML files at build time. Ideal for datasets that update infrequently (e.g., static location databases). Delivers fast page-load speeds via modern edge Content Delivery Networks (CDNs).
- Server-Side Rendering (SSR): Generates the HTML document dynamically on the server upon request. Ideal for massive datasets (100,000+ records) or platforms with real-time inventory updates.
- Incremental Static Regeneration (ISR): Combines the benefits of both by pre-rendering core programmatic pages while statically rebuilding individual pages in the background as underlying database records update.
Choosing SSR or ISR ensures that search crawlers encounter fully rendered, semantic HTML documents instantly, eliminating execution delays and conserving crawl resources.
4. Technical Architecture, Crawl Budget Protection, and Canonicalization
When scaling a web footprint to tens of thousands of programmatic pages, managing your crawl budget becomes an operational priority. Search engines allocate a finite amount of crawling resources to any given domain.
If your programmatic engine generates thousands of thin, low-value, or duplicate URLs, search bots will exhaust their crawl budget on junk pages, ignoring your core commercial pages.
To protect your domain's crawl budget and indexation health, adhere to these strict technical rules:
Explicit Canonicalization Rules
Every programmatic page must contain a self-referential canonical tag pointing strictly to its clean, canonical URL path:
HTML
<link rel="canonical" href="https://example.com/solutions/hr-recruiting-austin-tx" />
If your programmatic pages support filtering, sorting, or pagination, ensure all parameter-based URL permutations point back to the main unparameterized parent page.
Strict Indexation Logic and Noindex Rules
Do not force search engines to index incomplete, low-data, or zero-result programmatic pages. Implement programmatic noindex logic directly within your page header templates:
HTML
<meta name="robots" content="noindex, follow" />
Trigger noindex rules when:
- The entity record fails data validation checks (e.g., missing essential attributes).
- Search queries on the page yield fewer than a defined threshold of results (e.g., an internal directory search page with zero active listings).
- The page represents a duplicate permutation with minimal search volume differentiation.
Strategic Taxonomy and Internal Link Routing
Never publish programmatic pages as orphaned landing pages without internal link pathways. Search crawlers discover and evaluate pages based on how effectively internal link equity flows through a site's architecture.
Organize your programmatic URLs into clean, hierarchical subdirectories rather than flat root paths:
- Poor Flat Architecture:
[example.com/chicago-plumbing-services](https://example.com/chicago-plumbing-services) - Structured Enterprise Taxonomy:
[example.com/locations/illinois/chicago/plumbing](https://example.com/locations/illinois/chicago/plumbing)
To ensure authority flows naturally across your entire programmatic network, implement a strict three-tier hub-and-spoke internal linking hierarchy:
- Top-Level State Hubs: High-level overview pages (e.g.,
/locations/illinois) collect domain equity and automatically route crawlers down to every regional market. - Mid-Level City Hubs: Regional market hubs (e.g.,
/locations/illinois/chicago) group localized services together and pass authority to individual execution pages. - Child Service Pages: Highly specific target pages (e.g.,
/locations/illinois/chicago/plumbing) capture long-tail search intent while linking back up to parent hubs and across to peer services (e.g.,/locations/illinois/chicago/electrical).
Beyond vertical hierarchy, adhere to these explicit structural linking components:
- Parent-to-Child Links: State hub pages automatically link to City hub pages, which link down to localized Service pages.
- Breadcrumb Navigation: Implement dynamic, schema-backed breadcrumbs (
BreadcrumbList) across all generated templates to establish explicit structural hierarchy. - Peer-to-Peer Cross Links: Programmatically display "Adjacent Markets" or "Related Integrations" module sections at the base of every page to distribute internal link authority horizontally.
This systematic distribution of internal link equity directly improves user retention and session duration, reinforcing primary signals evaluated by modern conversion rate optimization frameworks.
5. Dynamic XML Sitemap Trees and Indexing Pipelines
Standard static sitemaps break down when managing enterprise-scale programmatic sites. Google Search Central guidance enforces a strict upper limit of 50,000 URLs (or 50MB uncompressed) per single XML sitemap file.
To manage indexing for large programmatic deployments, construct a dynamic Sitemap Index File (sitemap-index.xml) that acts as a master directory. This master index file routes search engine crawlers to specialized, auto-updating child sitemaps:
- Locations Sitemap: Dedicated XML feed housing all localized geographic programmatic URLs (e.g., 12,400 location pages).
- Products Sitemap: Dedicated XML feed containing dynamic e-commerce or product permutation URLs (e.g., 45,000 SKU pages).
- Integrations Sitemap: Dedicated XML feed organizing vertical SaaS integration and technology partnership pages (e.g., 8,200 integration pages).
Segment your child sitemaps logically by category, region, or entity type, rather than dumping all programmatic URLs into a single monolithic file.
Updating these sitemap feeds dynamically based on database changes ensures that search engines prioritize crawl budget toward freshly updated or newly deployed programmatic assets.
External Industry Benchmarks & Technical Standards
- Review official indexing limits and crawl management guidelines at Google Search Central.
- Validate structured data markup implementations against standard protocols defined at Schema.org.
- Explore technical web accessibility and rendering recommendations through the W3C Web Standards Consortium.
Key Takeaways
- Data Normalization Is Mandatory: Build robust, validated entity records before generating pages. Incomplete datasets create thin, low-quality pages that damage domain health.
- Render Server-Side for Speed: Use Server-Side Rendering (SSR) or Static Site Generation (SSG) to present clean, fully executed HTML to search bots on the initial crawl.
- Control Crawl Budget Proactively: Protect search engine crawling resources using strict self-referential canonicals, programmatic
noindexrules for zero-result pages, and dynamic XML sitemap trees. - Architect Structured Taxonomy: Organize programmatic URLs into hierarchical directory pathways with breadcrumb schemas and automated peer-to-peer internal linking blocks.
- Design for Answer Engine Optimization (AEO): Inject structured JSON-LD schemas alongside clear data tables to earn citations in AI search engines like Google AI Overviews and Perplexity.
Scale Your Search Architecture with Atlas Digital
Building a scalable programmatic SEO engine requires a multi-disciplinary approach across data architecture, web engineering, enterprise content design, and conversion rate optimization.
At Atlas Digital, we build high-performance programmatic search architectures that transform enterprise datasets into sustainable, high-converting organic growth channels.
Whether you are scaling a multi-location brand, expanding a SaaS integration footprint, or modernizing an enterprise search presence, our specialized engineering and growth teams are ready to help.
Connect with Atlas Digital to audit your technical architecture and engineer a scalable programmatic search pipeline today.